AI: The exploration phase

One of my broad personal interests has long been how what might be described as digital tools can facilitate human cognitive tasks. Many of us might accurately be described as knowledge workers. What this work involves varies with occupation and avocation, but, by definition, our work largely depends on cognitive (thinking) behaviors. The cognitive tasks that are employed vary in type and frequency of application across categories of knowledge workers so it follows that the ways in which technological tools might be of value will vary as well. I happen to be an educator.

This was perhaps a long way of setting up my argument which involves the application of AI. We are at a point of discovery when it comes to how the recently available AI tools will be of value in the many specific niches in which AI may support us. I am past the point of worrying about whether AI tools are a problem for education and the discussions of how potential problems might be countered. This took about a week. Our new reality seems obvious as AI tools for research and content production now seem to be arriving daily. It seems obvious we should commit to a period of exploration and evaluation (formal and informal). I think this is what OpenAI was hoping for with the release of ChatGPT. What creative uses will emerge and how well do they seem to work? In what specific aspects of work do these tools as they exist in their present form offer functions that can be identified and shared? Worrying about evaluation and control can wait until we have more experience.

I have an example of what I mean by a niche. The example may or may not be something you relate to in your own situation. If it fits, great. If not, consider it an example of the type of problem identification I think is valuable in searching for applications of a new capability.

One exploration

As a writer for a specific community (educators interested in what research might say about practice), I do and describe some of my own research, but I also spend a great amount of time combing the published literature for studies that might be relevant to what I describe for others. Like so many areas of the sea of information that could possibly be examined, what might be relevant to my interests is immense and growing and quite challenging to explore. It gets more challenging. The research in areas that involve human behavior is very different than say research in chemistry. Human behavior seems more messy and complicated and you encounter bodies of work that seem on the surface to be very similar and yet produce inconsistent and sometimes contradictory results. Those who don’t go deep can easily make pronouncements based on a given study that someone else can challenge based on a different study. It is frustrating to those of us who do this work and I am certain even more frustrating to those who consume our work only to find that what we propose can be questioned.

Here is perhaps an easier way to explain at least part of my challenge. On any given topic (e.g., Should students take class notes in a notebook by hand or using a laptop or tablet), there are both studies asking this straightforward question and there are studies dealing with the underlying mechanisms. Since straightforward comparisons often generate inconsistent results, a careful knowledge worker must review the method section of the studies carefully to try to identify differences that might be responsible for the inconsistencies and then try to locate other studies that may bear on the importance of differences in the methodologies. You find yourself trying to make a simple decision facing maybe hundreds of documents that may each take an hour or so to carefully review. 

So let’s start with the task of identifying the potential group of studies that may be relevant and making the decision of which of these documents should time be invested in reading. It may seem a small thing, but we may be making decisions that could easily impact days of labor.

Stages in useful content identification

My workflow typically follows a three-stage process.  

  1. Identify potentially relevant papers
  2. Evaluate papers to determine potential
  3. Read papers

Stage 1

Most folks who have a content location challenge probably now assume a Google search is how to proceed. I tend to work a little differently. I usually begin with a credible source familiar to me. I examine the reference section of this source, but I also use two online services. The reference section identifies studies cited by the author(s) of the paper I have already found valuable. These papers are older, but may identify studies producing conflicting conclusions or complementary studies using somewhat different methodologies, different participant populations, or other potentially informative variations.

I then enter the title of the paper into one of two search services – Google Scholar and Research Rabbit. 

Google Scholar extends the value of the existing list of resources I am now aware of in a forward direction. In other words, it lists other later studies that have cited the study I started with. Using Google Scholar I can review the abstracts of these later studies and perhaps find other relevant studies. 

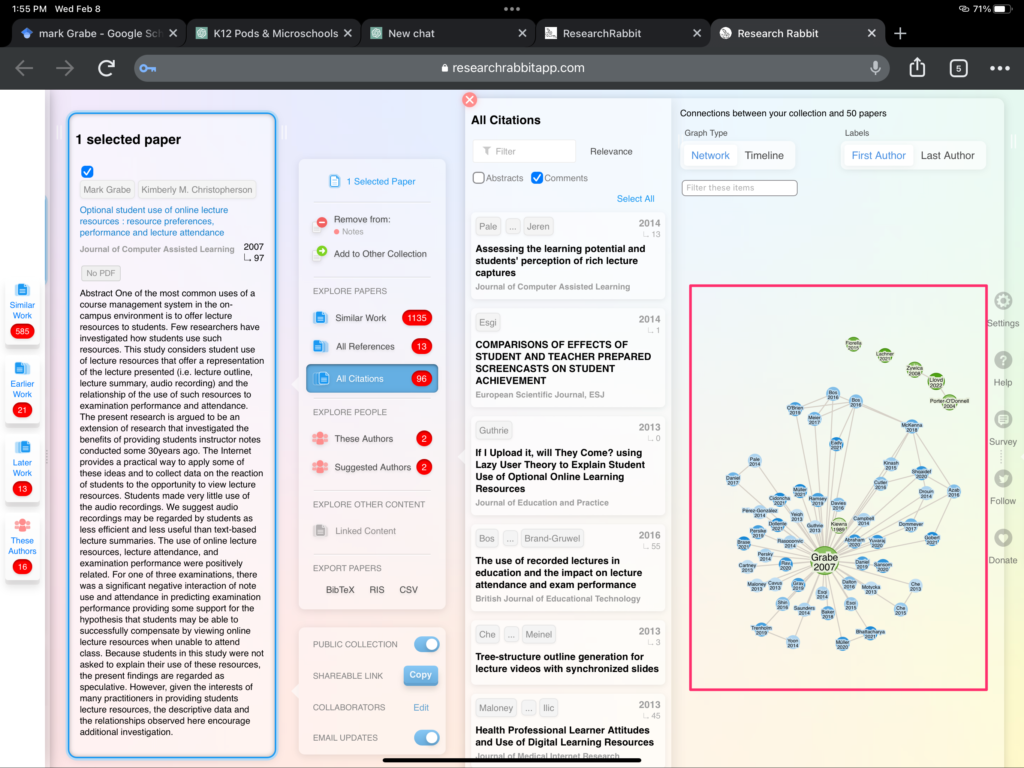
Research Rabbit extends the power of Google Scholar in both directions. It moves both forward and backward and forward for multiple “generations”. These data are returned as individual abstracts and citations, but also as a graph showing additional interactions. By “seeding” the service with several related papers it is possible to identify papers that are commonly cited together which are then proposed as being of greater value. The following image shows an example of a graph (red box) for the paper I am using here as an example.
There are several other tools that offer similar capabilities, but these two tools typically provide me plenty of resources to consider

Stage 2

Now what. I can review the abstracts of papers that seem relevant to prioritize a bit, but I keep hoping that something more would be available to get me started.

I wondered what I could learn with ChatGPT and I have been experimenting. My exploratory strategy has involved asking ChatGBT for information about papers I have written. The idea is that I know the information in the paper and I am trying to determine if a given tool will provide this information. Would I be able to ask questions about other papers and generate answers that are valuable and that I could trust?

The following is an example of this exploration and it is the text generated by my interaction. My inputs are bolded. I can enter a title for the paper and GPT will generate a credible summary. I would not offer this summary as different from the abstract, but it turns out to be similar and ChatGPT obviously can find information about a specific study based only on the title. This alone is at least interesting.

Summarize the journal article Optional student use of online lecture resources: resource preferences, performance and lecture attendance

The article investigates the optional use of online lecture resources by students, including their preferences for different types of resources and the impact on performance and lecture attendance. The results suggest that students have diverse preferences for online resources and using these resources can have a positive effect on performance, but may not necessarily affect lecture attendance.

Provide additional details

The study aimed to understand students’ preferences for online lecture resources, such as videos, slides, and lecture notes, and how these preferences impact their academic performance and lecture attendance. The study found that students have different preferences for different types of online resources, with some students preferring videos while others prefer slides or lecture notes. The results also showed that the use of online resources can have a positive impact on students’ performance, but there was no significant effect on lecture attendance. This indicates that students may use online resources as a supplement to attending lectures, rather than as a replacement. The results of this study provide valuable insights for educators looking to incorporate online resources into their teaching.

What statistics were used to analyze the data from this study

The information on the statistics used in this study is not specified in the description given. To know more about the specific methods and statistics used in this study, it is best to refer to the original article.

How was class attendance determined

The information on how class attendance was determined in the study is not specified in the description given. To know more about the specific methods used to determine class attendance in this study, it is best to refer to the original article.

What were a couple of the preferences for online notes the study identified

The information on specific preferences for online notes identified in the study is not specified in the description given. To know more about the preferences for online notes identified in this study, it is best to refer to the original article.

I am guessing ChatGPT is limited exactly as it suggests. The full published study requires paid access either by a library or individuals and this AI tool’s knowledge base does not include this information.

Elicit

Elicit uses AI to provide deeper insights than I was able to generate with ChatGPT. I doubt this is the advantage of the AI engine it uses, but most likely the result of the knowledge base it can access and the presets to look for specific things. Beyond the presets, Elicit provides the opportunity to ask custom questions and I was able to get answers to some but not all of the questions I failed to find answers for using ChatGPT. Sometimes I had to rephrase a question several times to generate the answer I knew was there. What I really wanted but could not get was a summary of the Methods section. I don’t need the results because the results are just math and can be approximated from the Abstract. The key to answering many important questions is the Methods that are applied as with this information one should be able to find factors necessary to interpret the Results and possibly explain differences between studies.

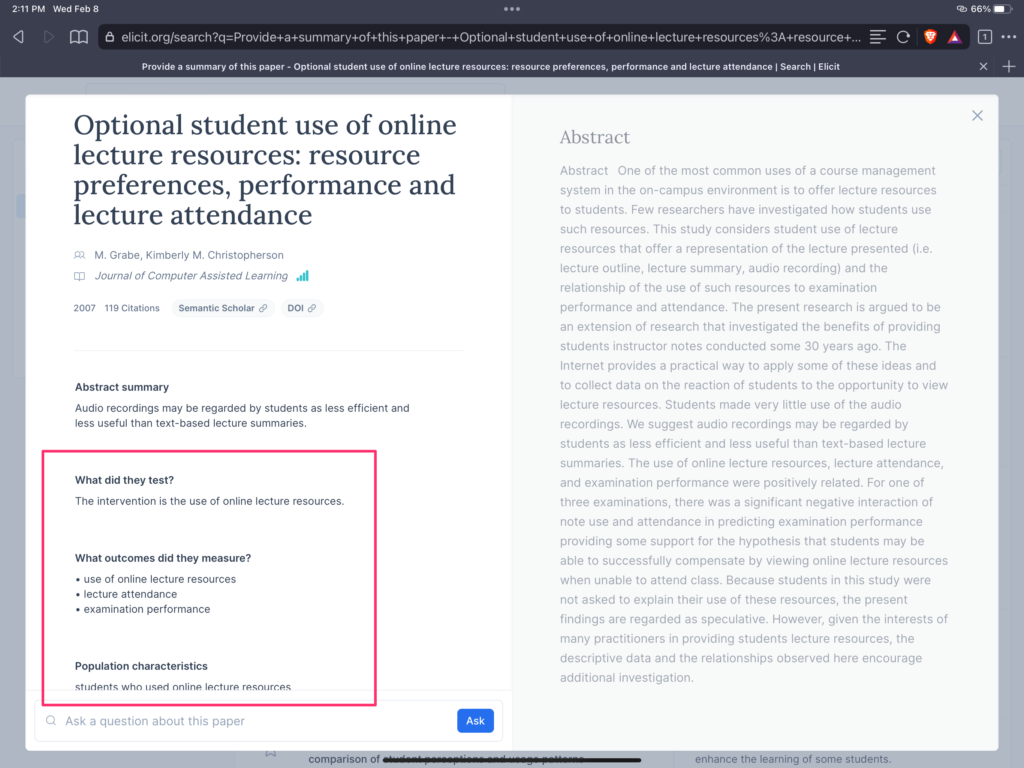
I recommend others with goals similar to my own take a look at this AI tool. The following images offer a peak. Some of what I describe as presets are shown in the red box in the first image. The opportunity to ask specific questions about the study is shown in the second image.
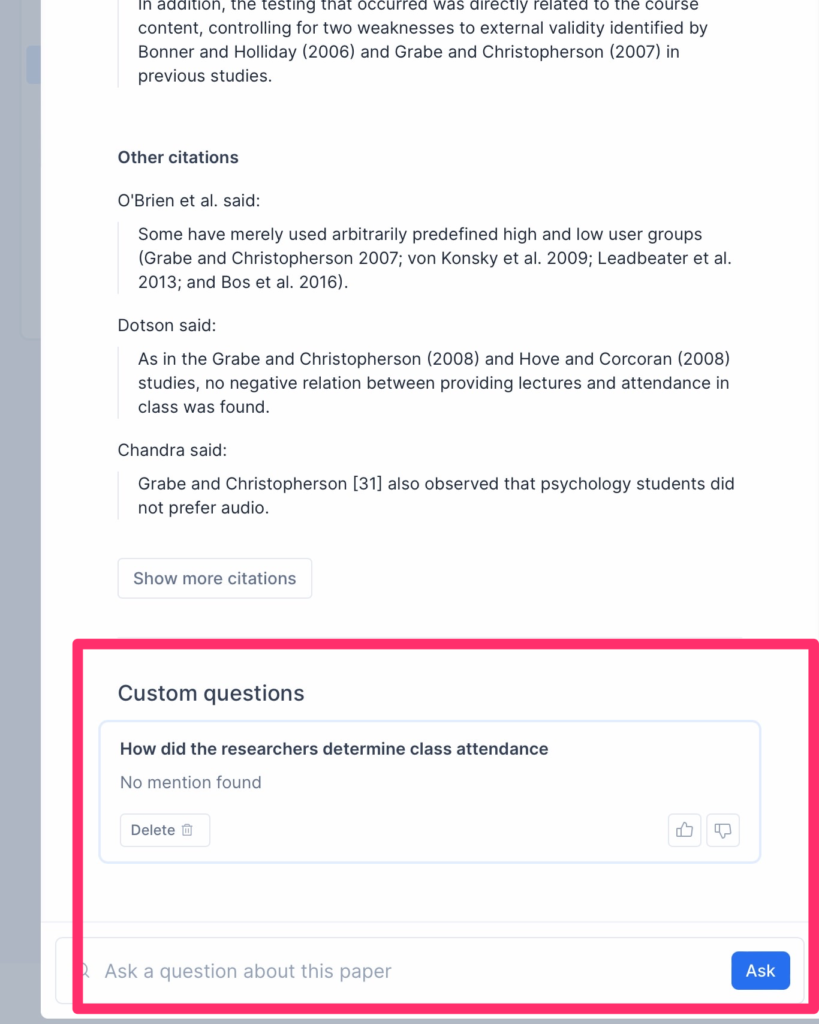
T

The summary and other information provided by Elicit was more detailed than the summary provided by ChatGPT. 

Stage 3

Now it is time to make a few selections and invest the time required to read papers predicted to be most valuable. This ends up being a never-ending process with new questions emerging and reuse of the same tools over and over again.

My point. It is time to explore. I have made a start on exploring AI tools for my own niche interests and perhaps I have offered some ideas you might use. Beyond that, I think this is the stage we are at and it would be useful for more individuals to see what AI tools offer for their own personal needs and share what they discover.

Loading

Exposure to AI

There is so much attention to AI with the release of ChatGPT I know most educators have wondered what the future holds. I propose a simple step that offers some insights into the capabilities of AI as a way to test the waters.

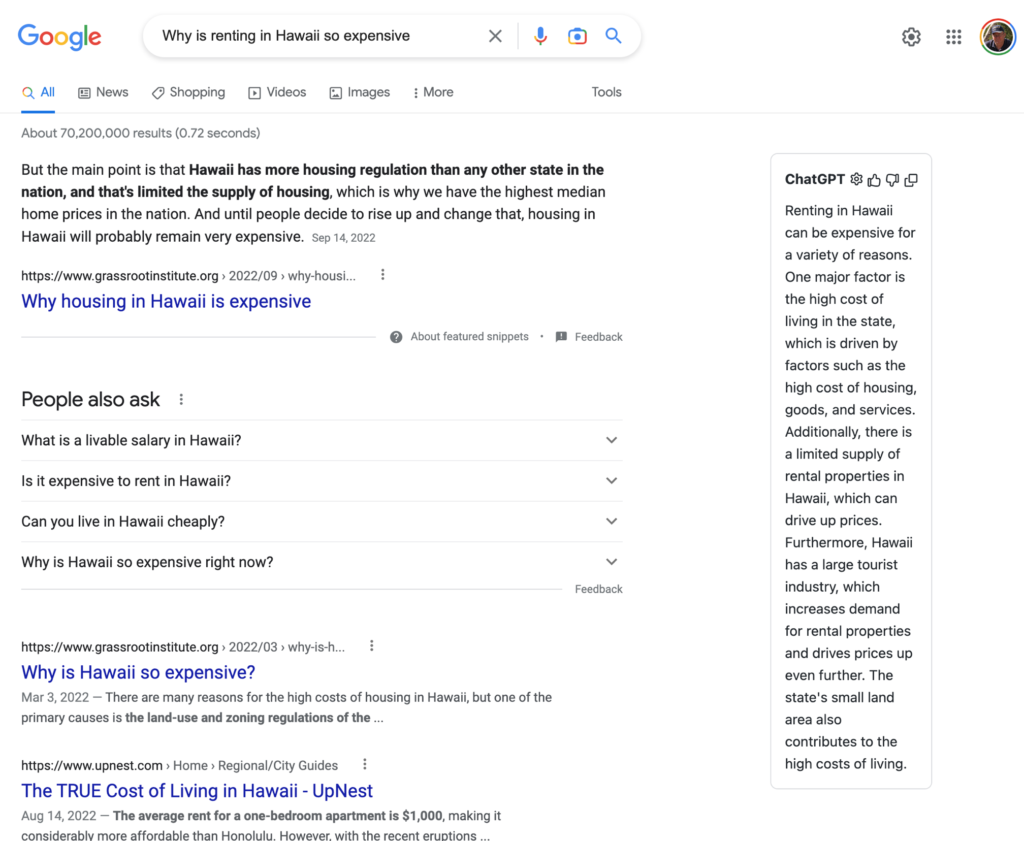
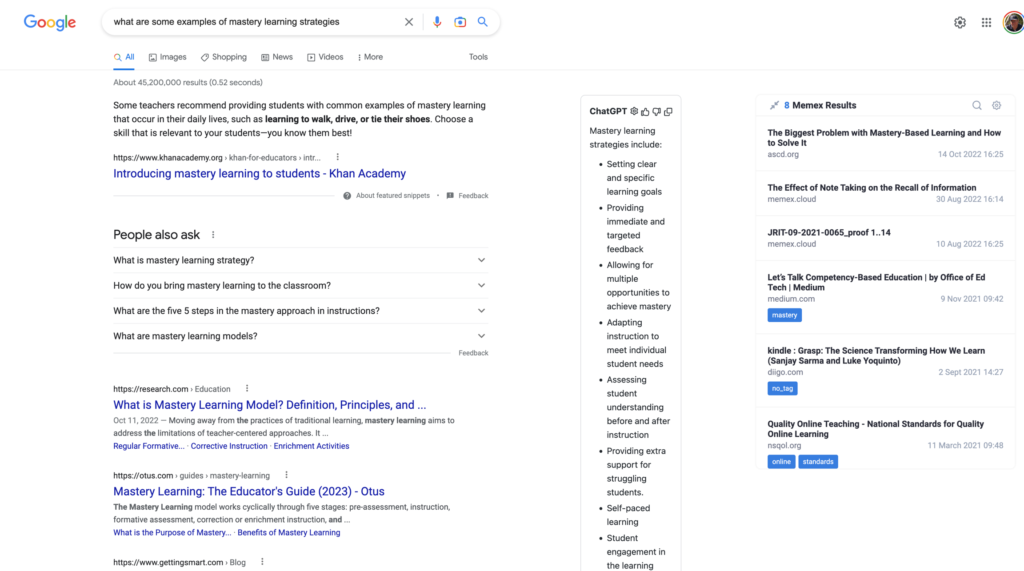
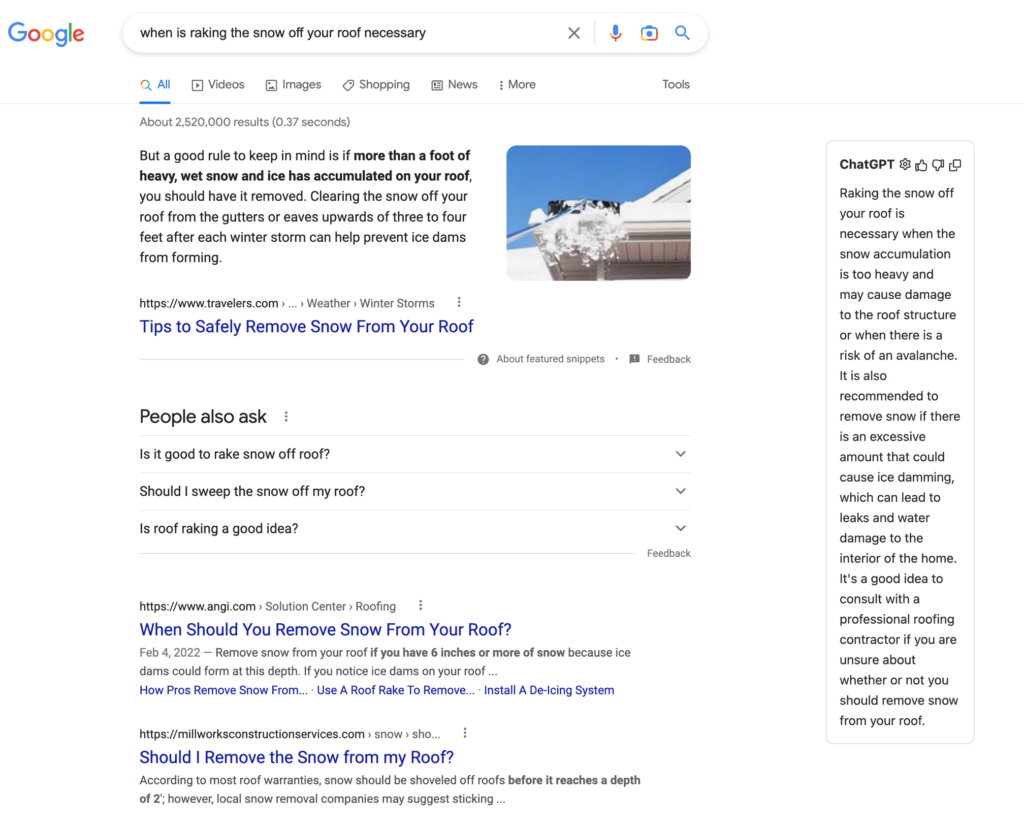
There is a Chrome extension that generates side-by-side Google search results and ChatGPT replies to the same request. Adding an extension is not that difficult. The site makes the install fairly easy. You do need to create a ChatGPT account (you will be prompted) and this has been challenging because the service has been overwhelmed and persistence is required. After using this extension, you can move beyond this experience to submitting requests directly to ChapGPT.

Here are some examples I generated based on questions I happened to have at that moment. The Google results appear to the left and the ChatGPT response to the right.

Q. When is raking snow off your roof necessary?

Q. 2 – Why is renting in Hawaii so expensive?

Q. 3 – What are some examples of mastery learning strategies? (the third column was generated by MEMEX which is a note-taking tool I use and that offers any notes I happen to have that seem relevant).

Loading

Most Popular in 2022

Identifying the most popular posts from the previous year is a common thing for bloggers to do. We like looking at our stats and perhaps others may have missed a popular post for one reason or another.

Here are my top three posts on this blog for 2022

Hotspots with Google Slides.

Shape-shifting Portfolio People

Hyperdocs, WebQuests and Other Teacher Created Designs

Here is the interesting thing about these posts. None were written in 2022. I was puzzled by this discovery until I looked at some of the other stats for the year. These stats include the referrer for visits to this blog. People might just bookmark this site and visit it to see what I have written. A related approach would be to use an RSS reader that follows multiple blogs and shows when anything new has been posted. This is the primary way I identify new content on other blogs. Twitter and Mastodon are linked to this blog and a short announcement appears when I write something new. So, there are connections from social media announcements. Finally, blog posts are followed by search engines and posts may appear in the list of hits when a search engine is used.

The most frequent way for others to come to this blog is through the use of a search engine. This is probably the reason older posts are most frequently visited. It might also mean I have not cultivated enough Twitter followers. It probably indicates I am old school in relying on RSS to follow bloggers and this discovery method has fallen out of favor.

Whatever the access method, I appreciate your attention to the topics we both seem to find interesting. Happy New Year.

Loading

I was wrong about ChatGPT

Like so many, I tested the capabilities of the new AI tool ChatGPT and offered a personal assessment. While I immediately saw that the tool would have significant consequences for classroom practice and especially those educators who assigned writing to learn tasks, I proposed that a fix would involve requiring the inclusion of careful citations in work students submitted. The samples I had ChatGPT generate did not provide citations and my naive understanding of the corpus of content the AI was drawing on did not include citations for the content.

I was wrong.

It took multiple efforts to find how to phrase questions so that the material produced would contain citations and then how to actually view the full citations for the work mentioned in a generated product. The following example involved two requests and are a modified version of the topic I used as an example in my first post. I have highlighted the mention of sources.

Me: How can a semantic network explain the tip of the tongue phenomenon and list citations that support this explanation?

The tip of the tongue phenomenon, also known as TOT, is a common experience in which a person knows that they know a particular word or piece of information, but they are temporarily unable to retrieve it. A semantic network can help explain this phenomenon by providing a framework for understanding how words and concepts are related to one another in the brain.

In a semantic network, words and concepts are represented as nodes, and the relationships between them are represented as edges or links. When a person is trying to retrieve a word or piece of information, they search through their semantic network to find the relevant node. If the person is unable to retrieve the word, it may be because they are unable to find the appropriate node in their semantic network, or because the node is not well-connected to other nodes in the network.

One study that supports the idea that the tip of the tongue phenomenon is related to the organization of semantic networks is a 2013 study by J. K. Stanley and colleagues, which used functional magnetic resonance imaging (fMRI) to investigate the neural basis of TOT. The study found that during TOT, the brain exhibits increased activity in the temporal lobe, which is known to be involved in language processing and the organization of semantic networks.

Another study that supports the semantic network explanation of TOT is a 2001 study by J. M. McRae and colleagues, which used a computational model of semantic networks to investigate the retrieval of words during TOT. The study found that the model was able to reproduce many of the characteristics of TOT, including the feeling of knowing a word but being unable to retrieve it, and the ability to retrieve the word after a delay.

Overall, the evidence suggests that the tip of the tongue phenomenon is related to the organization of semantic networks in the brain, and that semantic networks can provide a useful framework for understanding this phenomenon.

Me: Provide citations that explain how the theory of a semantic network can explain the tip of the tongue phenomenon.

  1. Stanley, J. K., Marslen-Wilson, W. D., & van Hell, J. G. (2013). The tip of the tongue phenomenon: An fMRI study. Journal of Cognitive Neuroscience, 25(6), 891-900.
  2. McRae, J. M., de Sa, V. R., & Seidenberg, M. S. (2001). On the tip of the tongue: What causes word finding failures in young and older adults? Journal of Memory and Language, 44(4), 542-579.

Loading

The Twitter challenge

Twitter has been part of my social media environment since 2008. It took me some time to figure out if the service was good for anything and then I gradually found uses that brought my attention to the service on a daily basis.

 In the early days, most of the comments lacked any substance. Eventually, I found value when others with interests similar to my own began to link to blog posts they had authored or other online resources. I had originally relied on using RSS to monitor what others posted. Interest in RSS has declined. Why this has happened is unclear. Perhaps RSS seems geeky and intimidating to casual users. Twitter is easy.

I found it important to have my blogging platform (WordPress) automatically generate a tweet indicating I had added a new post. WordPress collects data on the way viewers connected to blog author’s content (e.g., direct, search, Twitter, referrals) and the amount of traffic I received from Twitter demonstrated the importance of sharing what I wrote to Twitter.

As the number of my followers on Twitter accumulated, it seemed I should Twitter to share whatever I had to say about anything. It became to use Facebook for longer content and Twitter for short comments. 

I now find myself trying to decide what to do about Twitter. I share two distinct types of information and I am unsure of the direction Twitter will go in the future. I don’t want my professional content (the shared links to my blog posts) to be tainted if Twitter becomes like TruthSocial. I am also concerned about building up a following somewhere else.

My present approach is to wait and see what happens with Twitter. I am also diversifying the sharing of links to my blog posts (Mastodon). We seem to be in a time of transition. 

Loading

Clip, Tag, Annotate

McIntosh (2019) describes the basic skills of personal information curation as Clip, Tag, Annotate and proposes that educators teach this sequence of skills first focused on a single information resource and then on multiple resources that would serve as material learning how to do something (e.g., pickle cucumbers) or create something (e.g., an original blog post). Secondary students might not do these things,  but these happened to be the last two curation tasks I completed so they were fresh in my mind as examples.  

Clipping

Clipping describes the process of finding something useful on the Internet and saving all or a portion of this content for later use. Tagging is the process of adding one or more useful labels to this saved content that should be useful in organizing multiple sources and locating these sources when needed. Annotation is the process of adding longer notes to the content created by someone else for the purpose of summarization or inclusion of personal insights related to the stored material. 

I have tried implementing this sequence of activities with OneNote, Google Keep, and Evernote which I think of as the main competitors in the low cost clipping and annotation services. My preference is Evernote. McIntosh wrote his article for educators based on his classroom use of Microsoft OneNote. To be fair, I pay for a fairly expensive version of Evernote, but there is a free version that should allow users to apply the techniques I describe here. 

Clipping is accomplished using an extension added to your favorite browser. I use Chrome, but the Evernote extension can be added to other browsers. While the process works a little differently, content can be added to Evernote from a phone, tablet, or computer. You have the greatest control when using a computer with the main advantage being the opportunity to store parts of a web source rather than the entire document. 

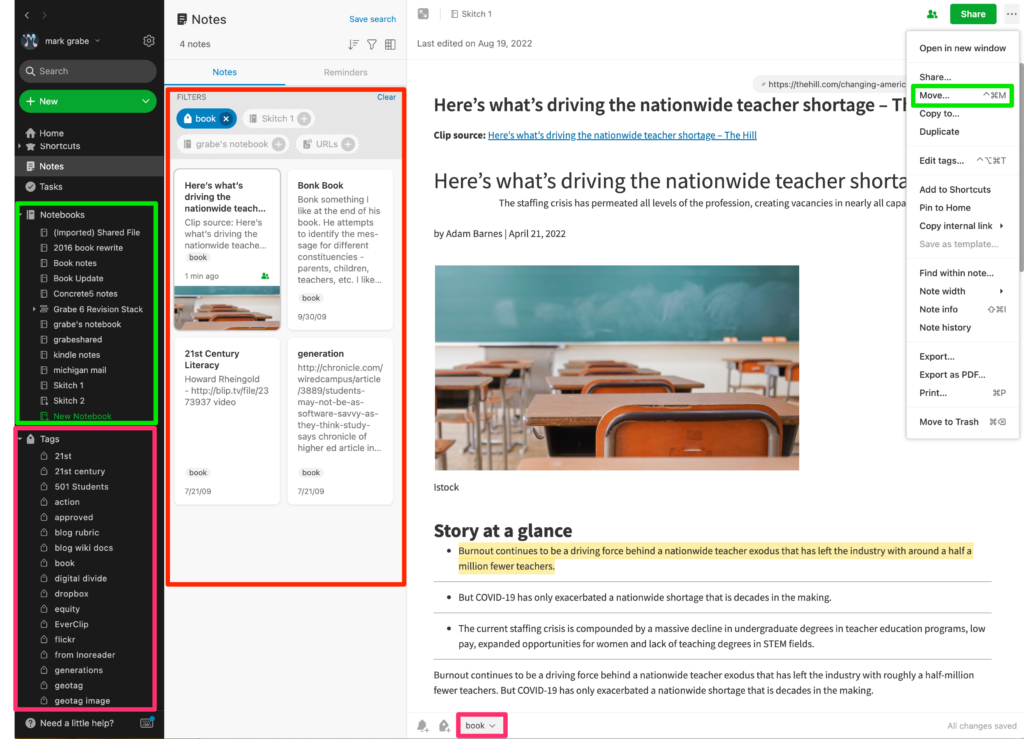
Understanding how Evernote works requires some additional comments. The following is the display as it appears on a computer. I will refer to this image at several points in this description. I think describing this as four columns works best. Actually, the software is flexible and offers the opportunity for different arrangements depending on personal taste. 

I will describe the columns from left to right. The first column offers the most general controls. I will concentrate on the note-taking capabilities and ignore other tools (e.g., tasks). Focusing on notes, the basic structure is that of notebooks as repositories of clipped content suited to a given purpose, notes, and additions to notes such as highlights, annotations, and tags. The areas contained in green squares involve notebooks. In the first column, you have the notebooks I have created. In the far right green box, you have an item from the drop down three dots (…) that allows the active clipped content (the third column) to be moved to a specific notebook. The red box in the first column identifies the existing tags. You create your own tags. These tags are listed in this box. The tagging of content will be described in the next section. The second column contains thumbnails representing stored content. Click on a thumbprint and the full document appears in the third column. Selecting a tag reveals the thumbprints for all content associated with this tag displayed within this column. So tags serve a filtering function for search.

Tags

A tag is a word or phrase used to classify content. Words such as topics or descriptors have similar meanings. In a system like Evernote, a user creates tags to categorize content as an organizational system that can make future retrieval easier. Hence, it is important when assigning tags to consider both descriptive accuracy and likely future application. Evernote offers a way to nest hashtags allowing a hierarchical classification system – e.g., computers – Apple, Windows, Chrome. In the image above, you see what happens when you select a hashtag. All existing content assigned that tag will be identified. Tags become a powerful organizational tool that becomes more valuable as the amount of stored content grows and as time passes making retrieval efforts more productive.

The creation and assignment of tags are distinct processes in Evernote. If a tag comes to mind perhaps in response to a newly clipped item, it must first be added to the collection of tags and then attached to that content item. When you first clip content, you will be asked to assign that clip to a notebook and to add desired tags. This is easy to see in the second image. New notebooks and tags can be declared at this time. Or, at a later point in time, clipped content can be moved to the desired notebook and new or additional tags can be added. With the desktop version of Evernote, this is a simple matter of dragging a tag or tags from the display of tags to the active document. 

Annotation

Annotation is used here to mean making additions to the stored material. Highlighting would be one example. With Evernote you add personal notations as part of the stored document. Think of this as being given a word processing document written by someone to which you can not insert text, links, or images. To make this what I consider a useful practice, I want to differentiate my additions from the original content so I change the text color to differentiate my summaries, comments, and questions. (See example in previous post)

Summary

McIntosh proposed clipping, tagging, and annotating as active reading practices students should learn to apply to digital texts. These are skills most students have not practiced and may not be allowed to apply to paper-based content. McIntosh proposed that students start with individual online content learning to add this content to a storage system, tagging the stored content, and then adding annotations that might be based on personal insights or based on a purpose assigned by the teacher. Using a common assigned online resource, the teacher can then comment on the choices made by individual students and perhaps then share student work to allow students to see how others have reacted to the same content. Once the basic skills are mastered, McIntosh proposes the system be applied to a research project requiring students to locate sources relevant to a goal, create a notebook, tag resources, embed annotations relevant to an integrative task, and finally generate this integrative project. Students should find this collection of skills relevant to many tasks they will be expected to complete for academic purposes and hopefully generalize the skills to the accumulation of resources they can apply more generally. 

McIntosh, J. (2019). Clip, Tag, Annotate: Active Reading Practices for Digital Texts. In Digital Reading and Writing in Composition Studies (pp. 176-188). Routledge.

Loading

Turn old computers into Chromebooks

Functional computers (Macs, Windows, and Chromebooks) age of support by manufacturers. Companies have decided they cannot maintain safe OSs over several different hardware updates. Google has generated a Chrome OS that allows users of these older computers a way to continue to use their machines as Chromebooks.

The following tutorial explains how I have used this OS (Chrome Flex) with a couple of my older machines.

Chrome Flex has been available for a couple of months now, but I had to wait until I returned home from my winter break and had access to a couple of old computers and a flash drive. One of the few challenges to spending the winter months in Kauaii is not having access to all of my stuff.

As I understand the history, Google purchased Cloud Ready and now offers a related product, Chrome Flex, at no cost. Chrome Flex is intended to offer a solution to two problems: 1) old Macintosh and Windows computers unable to run the current operating system intended for their brand and 2) Chromebooks that have passed the date at which they are still supported. I guess this is kind of the same problem. Often these machines are still functional and the older Macs and Windows machines may have the power and storage equal to or exceeding the less expensive Chromebooks. Schools and others interested in inexpensive alternatives might repurpose older machines with an operating system that allows them to function as Chromebooks and extend the useful life of these machines before sending them to the technology dump.

I have both an old Macbook Air and an old Dell that I have not used in years, but still keep around for experiments – usually a Linux install of some type. These machines are ideal for conversion to a Chromebook.

The process is easier than you might expect. All you need is a flash drive and an existing Chrome browser to which you add the Chromebook Recovery Utility (it is a Chrome extension). This extension allows you to create a recovery disk on the Flash Drive. Follow the instructions in creating the recovery drive and then use it with the computer you want to convert. I didn’t actually convert either of the old computers to a Chromebook – running the Chrome OS from the flash drive was good enough for me. I already have a perfectly good Chromebook, but maybe you don’t.

Two resources that will take you through the process – Android Police, HowtoGeek.

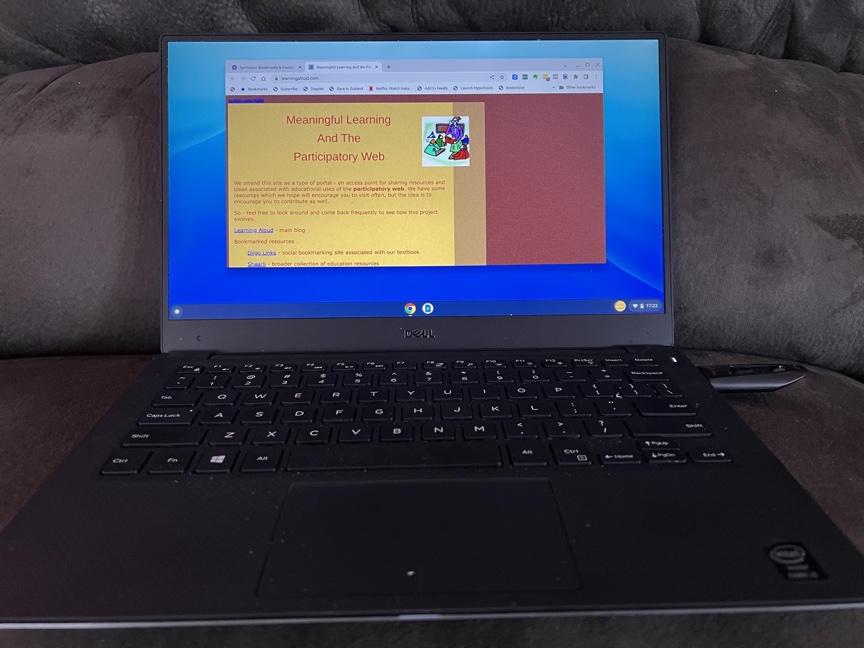
My Dell running as a Chromebook

Chrome Flex worked great. This has to be one of the most successful repurposing ventures I have tried.

What I learned

1) Don’t be cheap with the flash drive. I originally tried the install with a 32GB flash drive I found in a drawer. I had trouble with crashes and getting anything beyond very basic web browsing to work and nearly gave up on the entire adventure. They don’t offer this caution in the articles I read. I purchased a 512 GB flash drive (not cheap) and everything worked without any hiccups

2) When you access the flash drive from your older computer, you can try Chrome Flex from the drive or go ahead with the installation. I have learned from experience to try an experimental OS from the install drive first. I would get Flex to work on both the Mac and Windows machine, but I encountered problems with specific drivers on the Windows machine. It would not produce audio. I have encountered exactly this same problem when attempting linux OSs – the basic apps would work, but I would have trouble with drivers. Individuals with more experience or more patience may be to get my Dell to function without limitations, but I have never had a complete success with the Dell. Try running from the Flash Drive to identify such issues,

Loading